At Microsoft, our vision is to build a Frontier Firm: one where people and technology work together, combining human expertise, context, and judgment with technology that can extend intelligence throughout everyday work. The potential is significant: helping people create, solve complex problems, and make progress on some of society’s most consequential challenges.
But realizing that potential requires frontier infrastructure. The next phase of Super Intelligence needs a unified infrastructure engine that delivers more intelligence with greater efficiency, making AI more available, reliable, and sustainable across science, healthcare, education, and the economy. This is the work of an entire ecosystem, and precisely the vision we have advanced for years through our industry collaboration within the Open Compute Project Foundation.
Designing silicon in the loop with real workloads
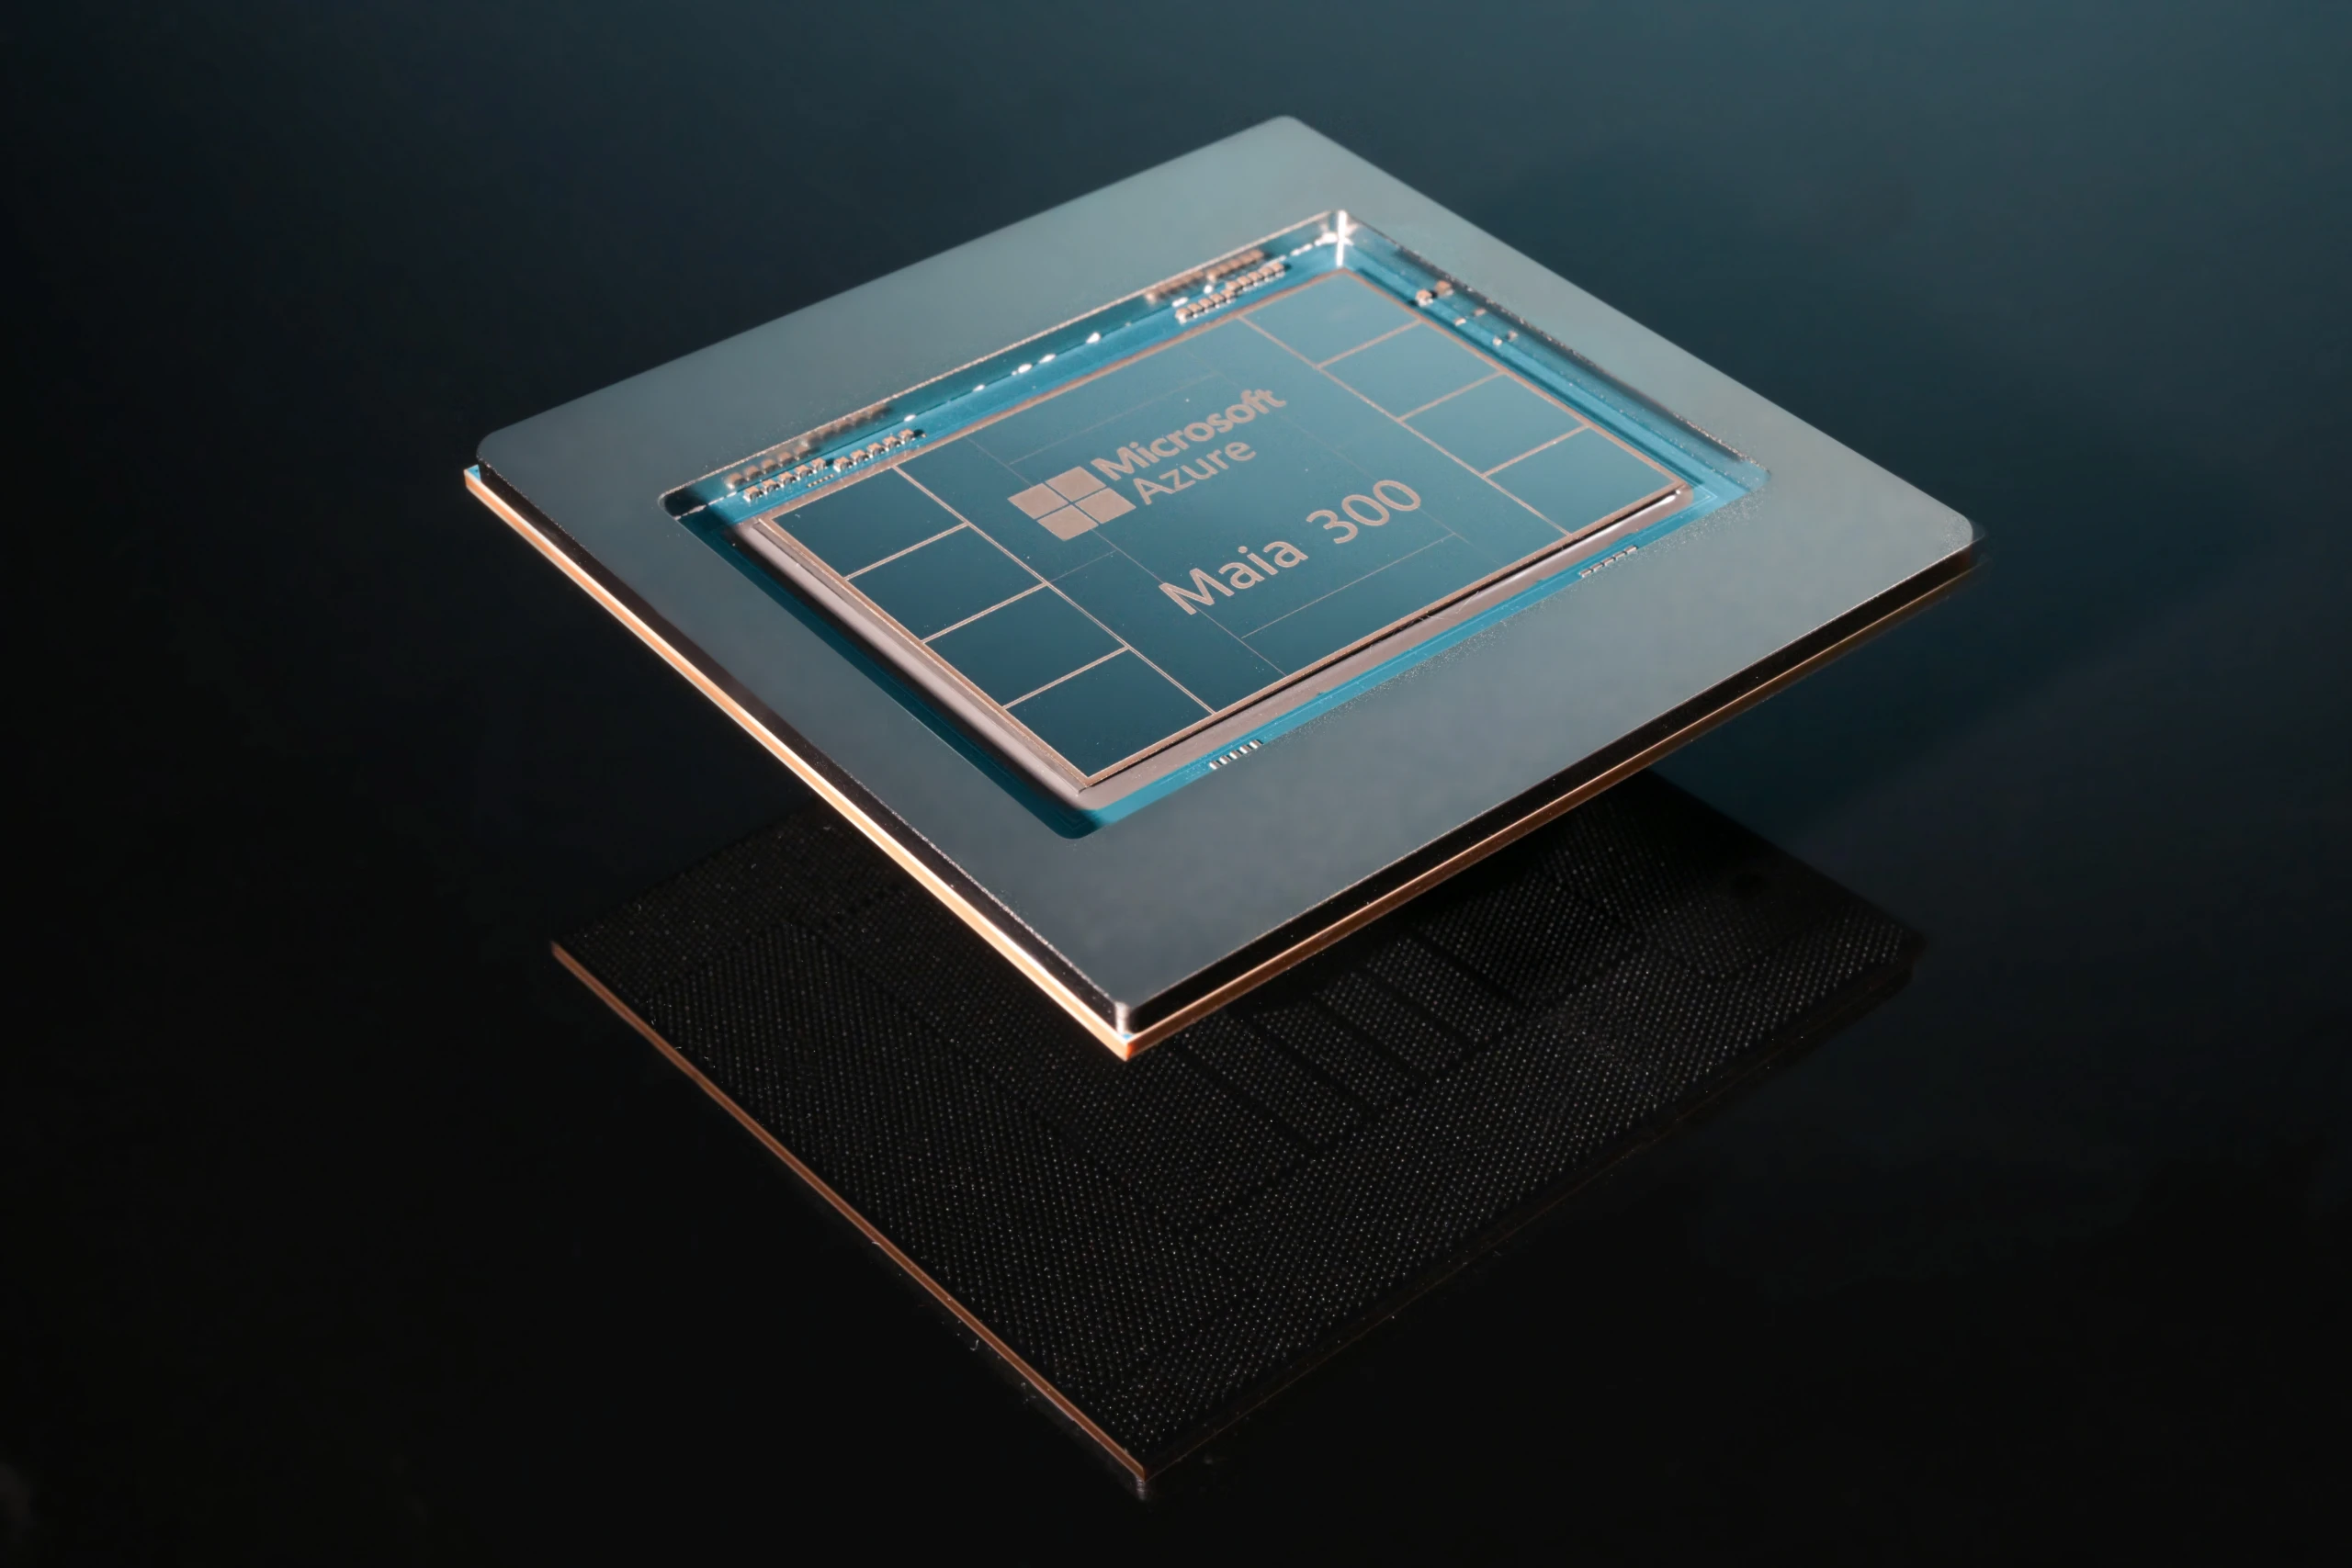
As we enter the next phase of Super Intelligence, inference is becoming the dominant workload and that’s where efficiency, latency, and cost really matter. Azure Maia 300, our next generation AI accelerator from our Maia family, advances the inference efficiency frontier. Maia 300 is a complete system designed for the new types of AI workloads emerging today: long-context reasoning, latency-sensitive conversational experiences, and sustained, multi-step agentic tasks. By improving efficiency across the system, we expect Maia 300 to deliver 40% more tokens per watt compared to leading GPU-based systems. And in a full 96-accelerator configuration, it delivers up to seven times the rack-scale token throughput of Maia 200.
Maia reflects our system co-design approach. It is designed alongside Microsoft infrastructure and production workloads, bringing models, application frameworks, kernels, communication libraries, systems software, and custom silicon into one optimization loop. Maia 200 is deploying across the United States, Europe and Australia and delivering up to 1.7x more tokens per watt for built-in AI capabilities in Microsoft Teams, Copilot and Cowork experiences compared with leading GPU infrastructure.
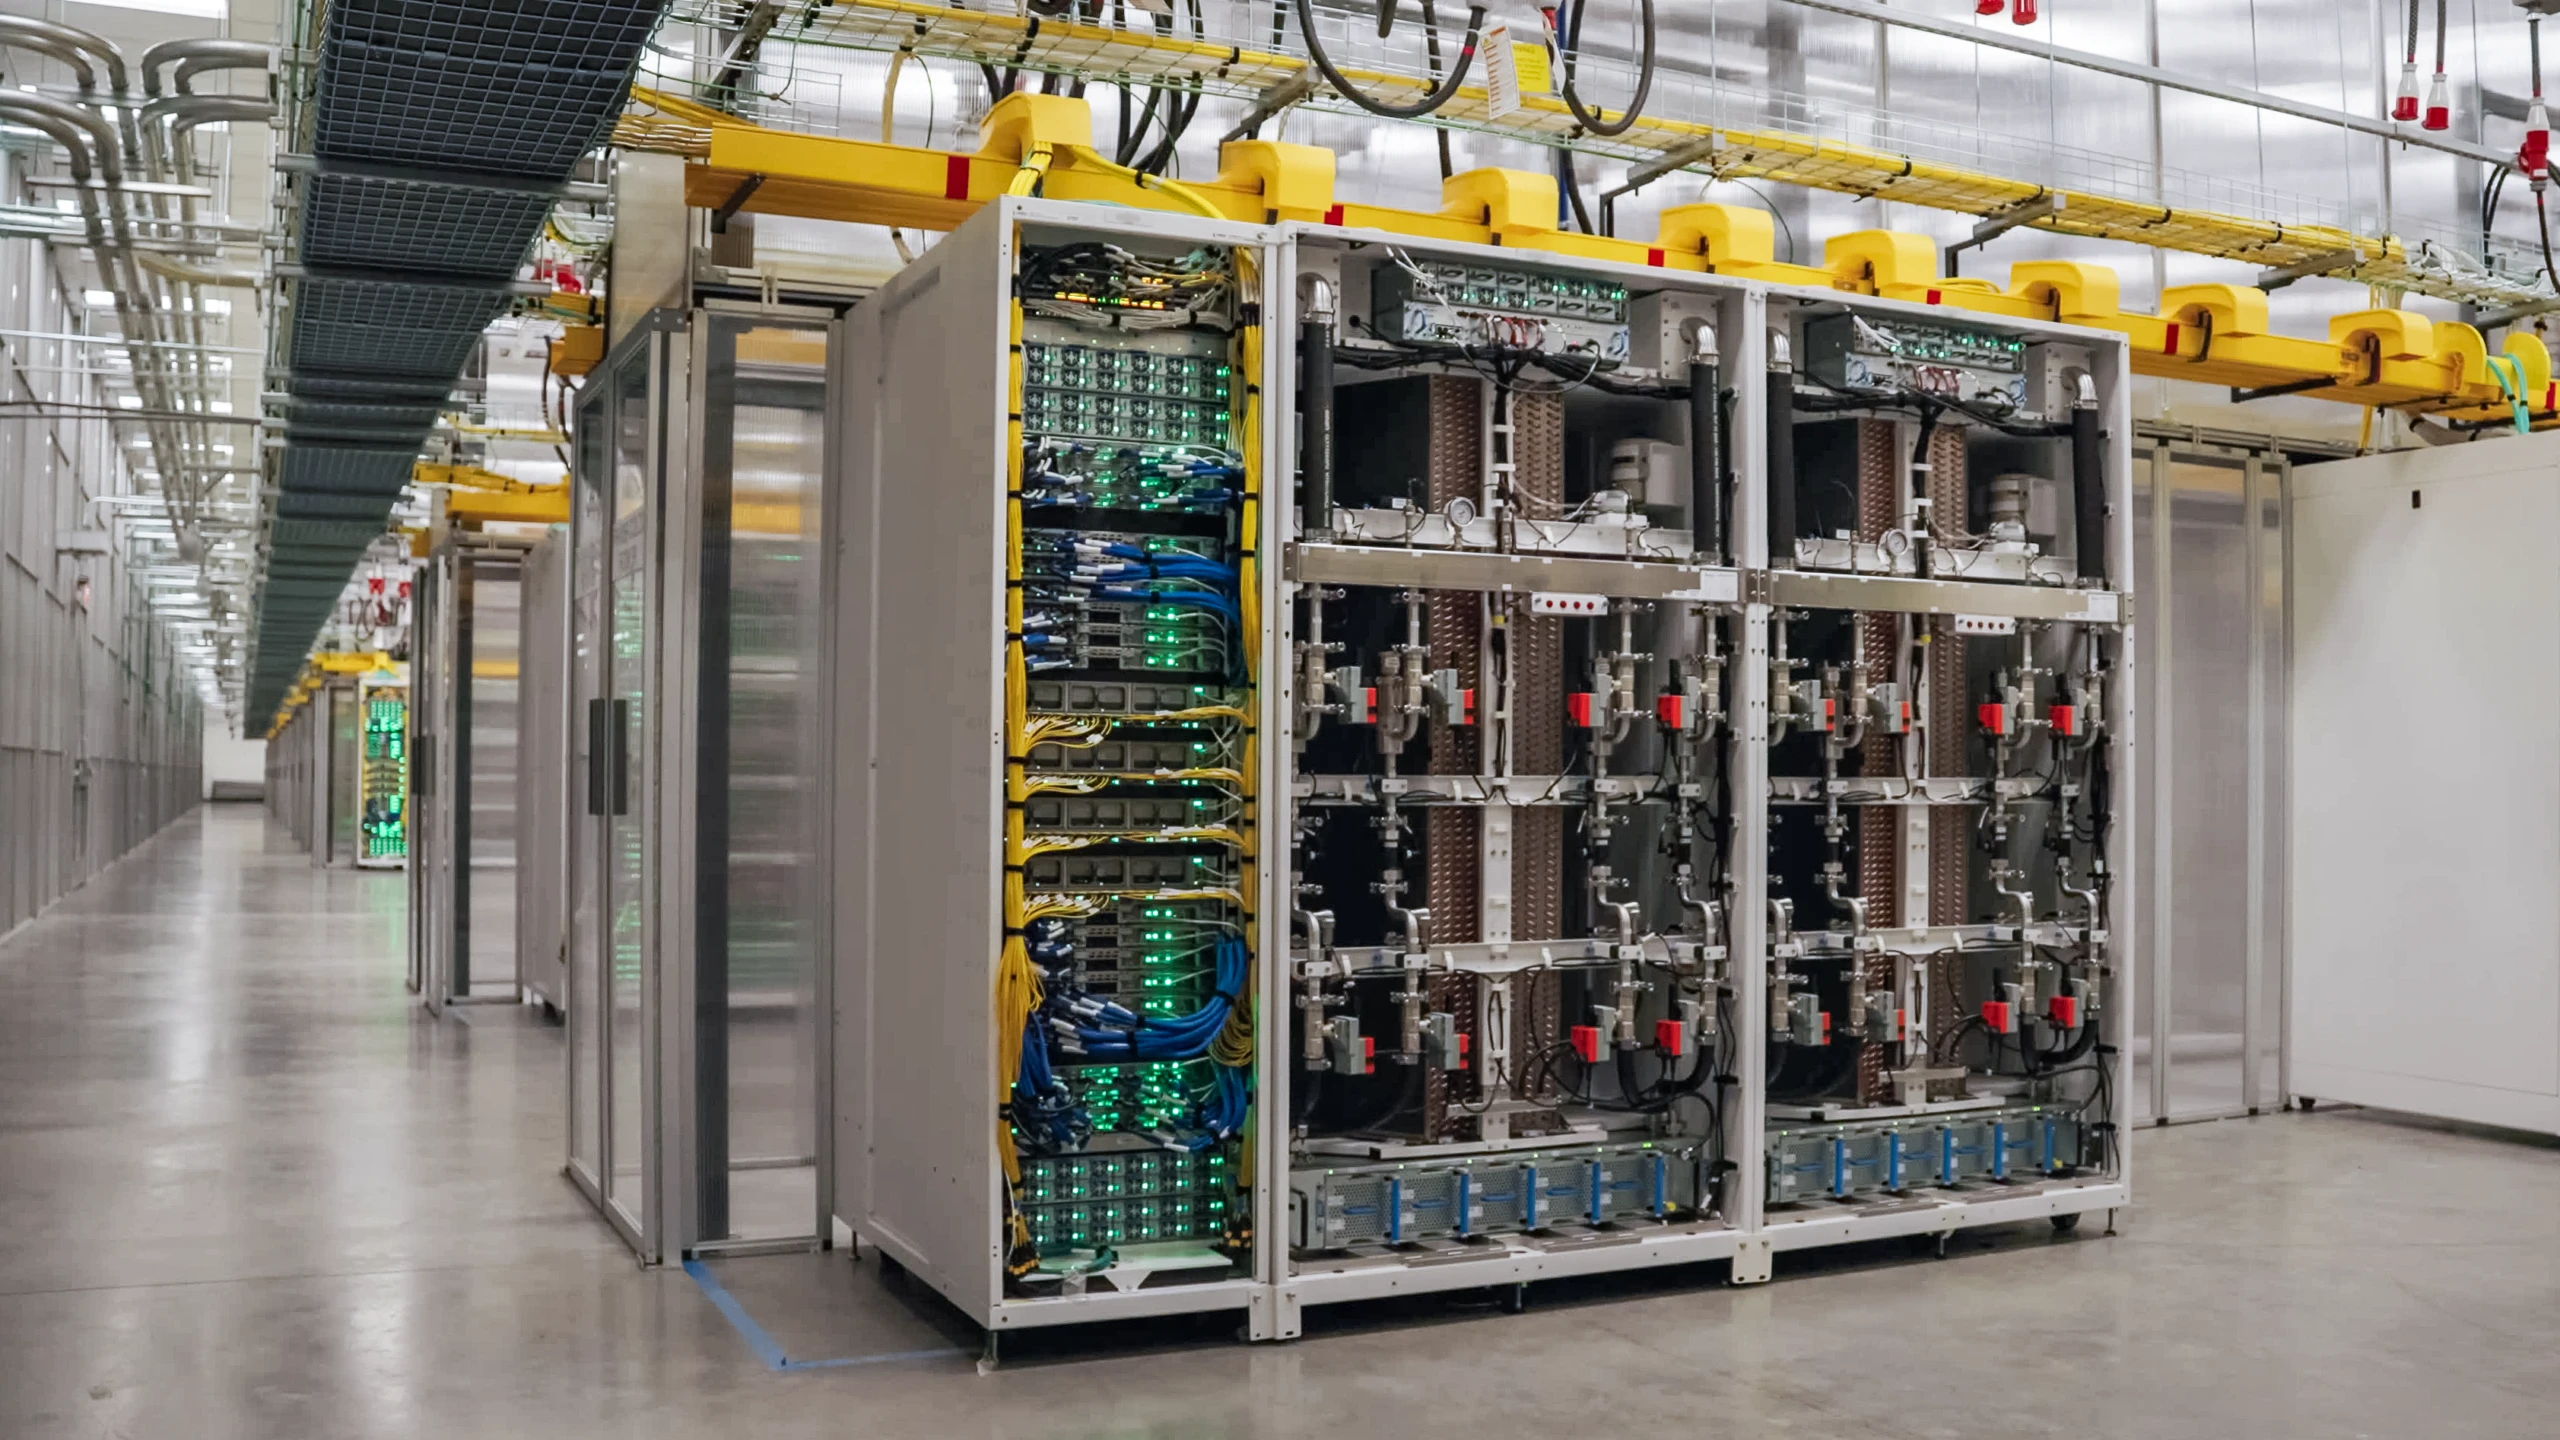
AI is not only about accelerators. Agentic workloads create entirely new demands on CPUs. Every agent interaction generates orchestration, data retrieval, memory management, and service calls that must occur quickly and efficiently. That is why we designed Cobalt 200 as an agent-native CPU. Cobalt 200 delivers more than 50% performance improvement over Cobalt 100 and reduces agent call latency by 33%, while providing 23% higher throughput on agentic workloads.
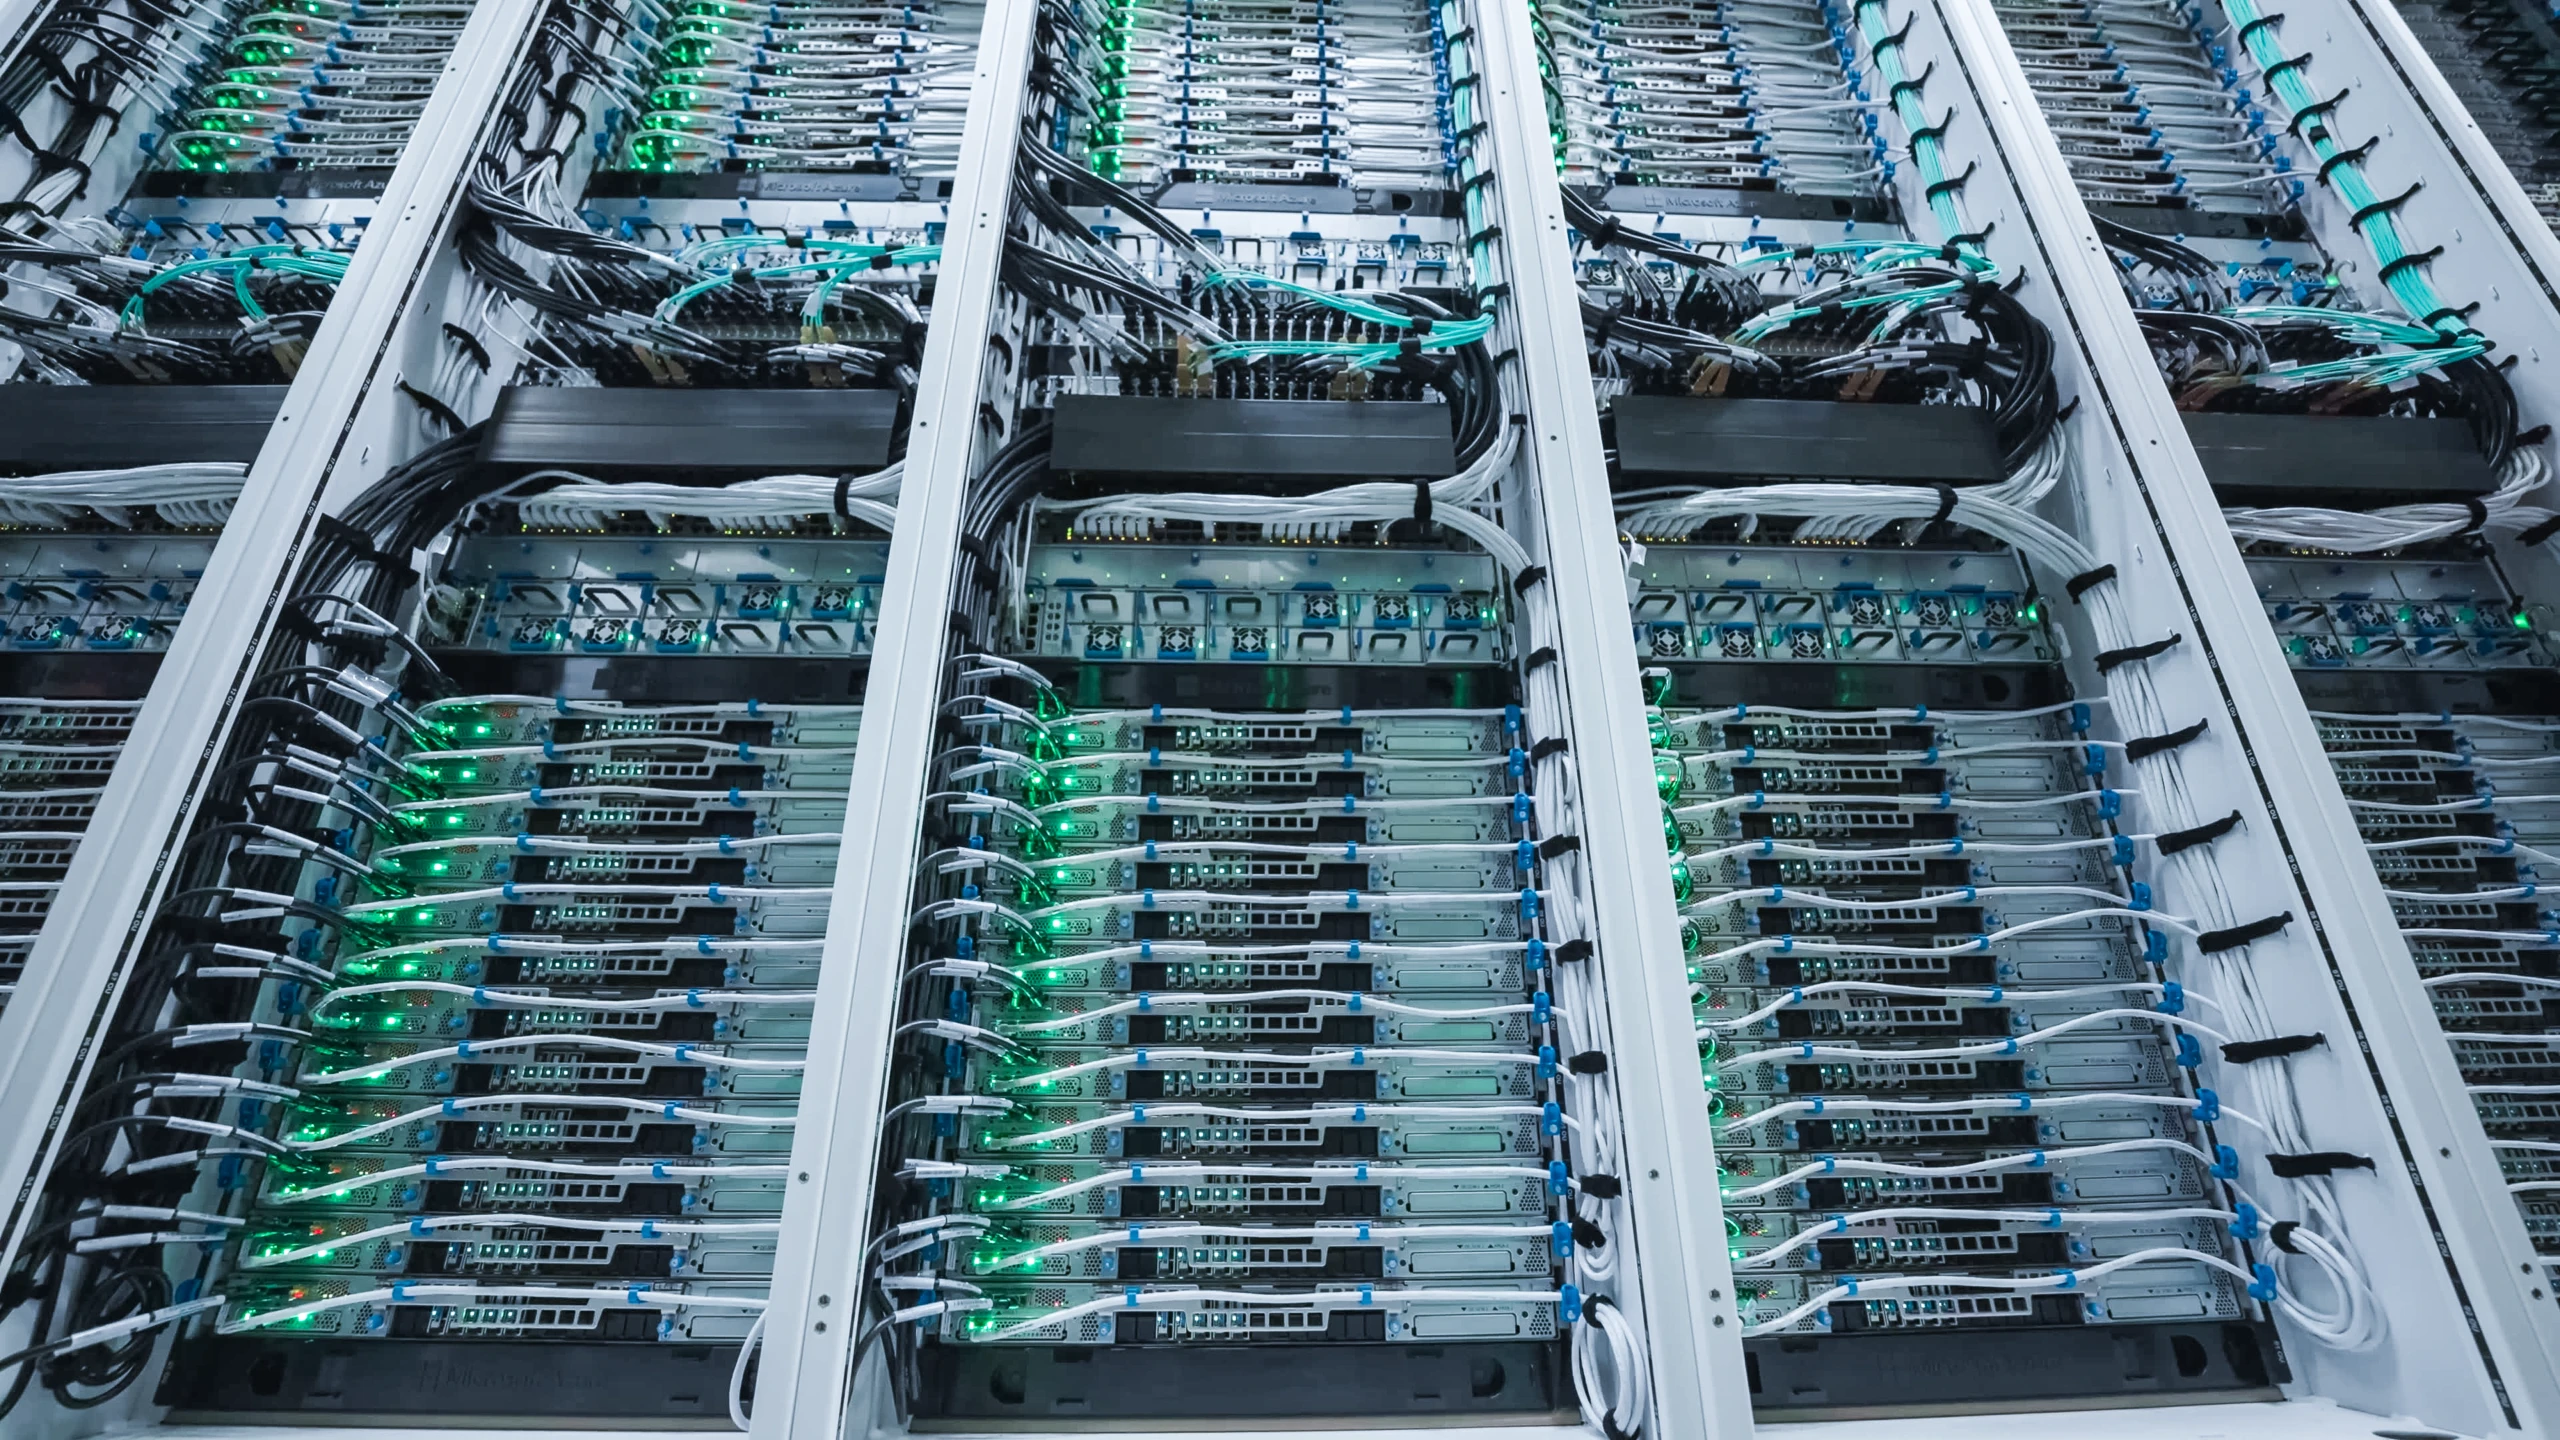
Maia and Cobalt are designed in the loop with our largest enterprise workloads. That gives Microsoft a unique advantage in tuning performance, reliability, and cost to exactly what customers need in production.
We are applying the same principle to storage and security. The Azure Boost Data Processing Unit moves compression, networking transactions, and security functions away from the CPU onto purpose-built silicon, enabling us to deliver four times more performance while using significantly less power.
And Azure Integrated HSM makes security part of the hardware foundation, with our in-house security chip in all new datacenter servers. It brings cryptographic operations closer to the workload while keeping keys protected inside the hardware security boundary—not exposed in application memory.
Building an open, resilient AI fabric
Compute creates intelligence and networks make it usable at scale.
Working with industry partners, Microsoft developed Multipath Reliable Connection (MRC), rethinking Ethernet for AI. Its multi-plane architecture scales beyond 100,000 GPUs with two network tiers, reducing power, complexity, failure points, and cost. By intelligently distributing traffic across multiple paths and through packet spraying, MRC limits congestion and maintains reliable performance for frontier-scale training.
We are also advancing open scale-up connectivity through Optical Compute Interconnect Multi-Source Agreement (OCI MSA). OCI, the first optical specification for multi-rack scale-up systems, enables high-bandwidth, power-efficient, multi-vendor infrastructure. Moving forward, we will continue to work with the industry to expand participation in OCI MSA.
In parallel, The Ethernet for Scale-Up Networking (ESUN) workstream brings together more than 175 organizations to define requirements for Ethernet-based scale-up networking. The group has released specification version 1.0 and is developing version 1.1 for later this year. Read more about our networking innovations with the open community.
Rethinking power from grid to silicon
AI infrastructure is also forcing a fundamental redesign of power delivery. Through OCP and the Open Systems for AI initiative, Microsoft is helping advance the industry’s transition toward 800 volt direct current (VDC) infrastructure.
Mt. Diablo, Microsoft’s disaggregated high-voltage datacenter (DC) sidecar architecture, separates power conversion from the compute rack so each can scale independently. It includes a modular design supporting approximately 100 kilowatts (kW) to beyond one megawatt (MW), with redundant feeds, telemetry and optional energy storage. Microsoft, together with OCP partners, contributed Mt. Diablo specifications v0.7 and v1.0 to OCP.
Microsoft and its partners are advancing solid-state transformer-based architectures to make power conversion more efficient, responsive, and scalable for next-generation 800 VDC datacenters. Through OCP’s Clean Backup Power initiative, we are developing open requirements for reliable backup systems that reduce reliance on diesel. In parallel, Microsoft collaborated with partners to release a common grid-interface specification to align utilities, operators, and equipment vendors as hyperscale power architectures evolve. Read more about Microsoft’s approach to 800VDC transition and scaling power infrastructure sustainably.
Cooling as a first-class design consideration
Microsoft approaches cooling as a datacenter-wide challenge, driving innovation from DC facility design to rack-level liquid cooling technologies.
Our third-generation Azure Heat Exchanger Unit, Mt. Atlas, nearly doubles cooling capacity compared to the previous generation while maintaining the same operational footprint. We are also contributing public reference architecture through OCP to help accelerate industry adoption.
At the datacenter level, Microsoft is advancing a zonal cooling strategy in its next-generation AI datacenters to handle the growing mix of liquid-cooled accelerators and traditional air-cooled systems. By tailoring cooling to the specific needs of each workload, and introducing multiple independent water loops, each supplying coolant at different temperatures, we aim to increase efficiency and performance while supporting Microsoft’s energy, carbon, and water reduction goals.
Open hardware security innovation
Microsoft believes strong cloud security is built through openness, transparency, and industry collaboration. This principle is reflected in our founding role in the Confidential Computing Consortium, our work to establish Caliptra as an open-source silicon root of trust, and our contributions to the OCP S.A.F.E. security conformance framework. As AI reshapes the cybersecurity landscape and advances in quantum computing introduce new cryptographic risks, protecting the keys and credentials at the foundation of digital trust has never been more important.
To address these challenges, and building on our commitment to security transparency and industry collaboration, Microsoft, Marvell, and Oracle are introducing Tessera Integrated HSM, an open-source initiative for integrated hardware security modules. Tessera Integrated HSM carries forward the workload direct attached HSM architecture introduced by Azure Integrated HSM, open-sourcing its architecture, specifications, protocols, drivers, software, firmware, and silicon to the broader community. Learn more about Tessera Integrated HSM.
Fleet resiliency at scale
As AI infrastructure scales, fleet reliability is essential to protecting customer workloads, capacity, and service quality. Through OCP, Microsoft has published common RAS, debugging, telemetry, and diagnostics specifications, while contributing work on hardware fault management, CPU and GPU management, and fleet memory fault management. We are using years of fleet data and using AI to validate, predict, and drive fleet actions aimed at preventing faults, pinpointing issues, and recovering more autonomously. Learn more about how Microsoft is advancing fleet reliability through industry collaboration.
Advancing sustainability across the infrastructure stack
Scaling AI responsibly means considering the full datacenter lifecycle to help reach our 2030 commitments to be carbon negative, water positive, and zero waste. As a company, we are committed to incorporating sustainability into how we design, build, and operate our datacenters extending to the communities where we build them. Through OCP, Microsoft is collaborating with partners on low-embodied-carbon steel and concrete—with pathways to reduce concrete emissions by more than 50% per cubic yard.
We are advancing waste-heat reuse, and helping develop Cloud Services Product Category Rules for consistent, auditable lifecycle-carbon reporting. Inside our datacenters, closed-loop liquid cooling, intelligent power management, and renewable-energy agreements help reduce resource use, while Circular Centers reuse or recycle more than 90% of servers and components. Beyond the datacenter, we are investing in local skills, partnerships, and infrastructure so the communities hosting this growth can grow with us. Read Microsoft’s 2026 Environmental Sustainability report.
Building the frontier together
Our vision is to help every organization become a Frontier Firm, uniting human expertise with AI in a continuous learning loop that turns knowledge and ingenuity into scalable intelligence. Realizing that vision requires full-stack co-design: silicon, compute, memory, networking, power, cooling, models, and applications working as one secure, reliable, efficient, and sustainable platform while giving customers choice without passing complexity on to them.
Such a future cannot be realized by a single organization. Through OCP, we are advancing open interfaces, sharing lessons from operating infrastructure at global scale, and collaborating across the industry so innovation moves faster, and the ecosystem stops solving the same problems repeatedly. Together, we can transform frontier innovation into infrastructure that makes intelligence accessible and affordable for every organization, in every industry, and across every region of the world.
At OCP Global Summit 2026, we invite the community to build that future with us.
Build for what’s next
Learn more about Microsoft’s systems approach to infrastructure.